Labeling
Training data labeling, human-verified
Send us raw images, video, audio, text, sensor, or 3D security data. Get back a labeled, checked, versioned training set in your format — labeled by our team, your team, or both.

What you get
A training set you can put your name on
Raw files go in. Each one is prepared, labeled, and reviewed, then delivered as a version with its paperwork.
A labeled, human-verified set
Every item annotated to your guidelines and passed through review before it counts as done.
In your format
Delivered back to your bucket in the schema your training code already reads. No reformatting on your side.
Versioned
Each delivery is a version you can diff, roll back, and cite — not a folder of loose files.
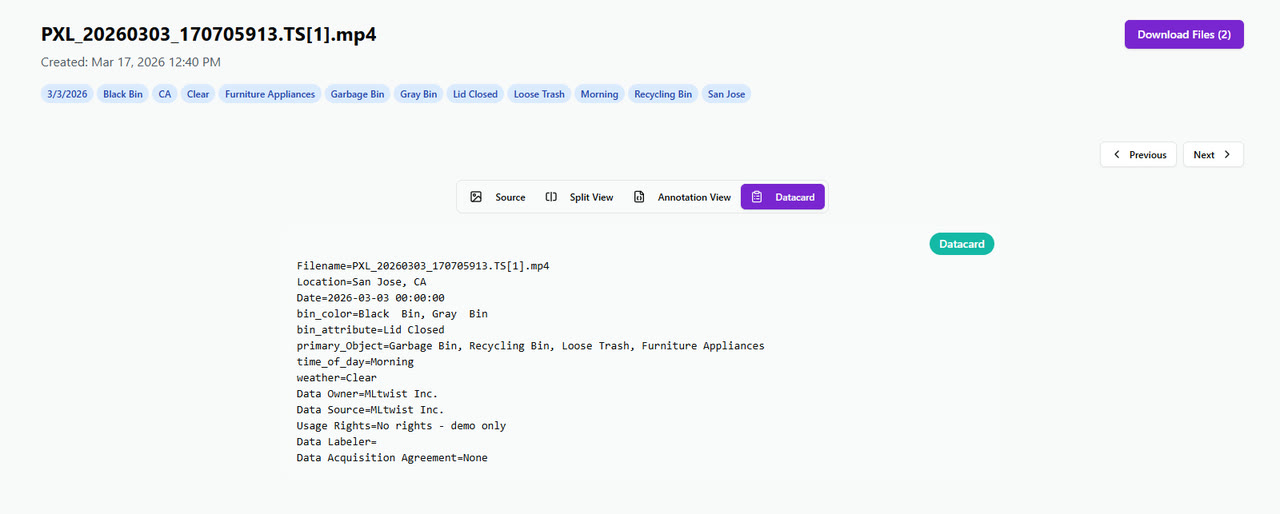
With a Data ID Card
A record of where the data came from, what touched it, and who labeled it. Audit-ready by default.
How you buy
Our team, yours, or both
Pick how the work is staffed. The tooling, QA, and delivery are the same either way.
Our team labels it
- You send data and guidelines; we staff, train, and run the work.
- Vetted annotators from our partner network, including domain and language experts.
- Scale up for a sprint and back down when it's done.
- You review samples and approve deliveries.
Your experts plus ours
- Your subject-matter experts review or label the hard cases.
- Our team handles volume and first-pass labels.
- One queue, one QA process, one delivery.
- Common for cleared, regulated, or specialist programs.
Your people, our tooling
- Your annotators work in MLtwist's labeling tool.
- Ontology builder, labeler and reviewer roles, consensus review.
- Workload, agreement, and time tracking per person.
- Add MLtwist capacity any time without re-platforming.
Modalities
Messy, multimodal, and regulated data included
Images
Classification, boxes, tilted boxes, polygons, and attributes.
Video
Frame and clip labels, object tracking, and event tagging.
Audio
Transcription, speaker and event labels, language coverage.
Text
NER, classification, extraction, and low-resource languages.
Sensor
Multimodal captures labeled together, with metadata merged in.
3D & security scans
X-ray and body-scanner screening data and other 3D scan formats.
Quality
QA you can measure
A label counts as done after it passes checks, not when someone clicks submit.
Consensus and peer review
Configure how many people see each item and what counts as agreement. Disagreements go to a reviewer, not into your set.
Automated checks
Schema, completeness, and anomaly checks run on every item before a human reviewer sees it.
Measured, per person
Agreement and miss rates by labeler and by class, so quality problems show up as numbers, not surprises.
Approval before delivery
Nothing ships until it passes review. Rejected work goes back with the reason attached.
Export + Data ID Card
Delivered in your format, with its paperwork
We map labels to the schema your pipeline expects and write each version back to your storage. Every delivery carries a Data ID Card.
- Origin. Where each file came from and under what terms.
- Transformations. Every step that changed it, which tool ran it, and when.
- People and vendors. Who labeled and reviewed it, and which companies touched it.
- Compliance. How each party meets your security and ethical requirements.
Prepare
Get raw data ready to label
- Ingest straight from Google Cloud Storage, Amazon S3, or Azure Blob — no local copies.
- Clean, deduplicate, split, and convert files before anyone labels them.
- Pre-label with foundation models so people correct instead of starting from zero.
- Merge metadata and companion files so annotators see full context.
Source
Don't have the data yet?
- Real-world collection to spec — video, image, audio, and text — with consent and PII handling built in.
- Nationwide video capture programs, such as ocean footage for a maritime company.
- Synthetic data to cover rare and safety-critical cases you can't film.
- Every sourced item gets the same QA and Data ID Card as data you bring.
FAQ
Common questions
Do I have to use your annotators?
No. Use our team, your team on our tooling, or both. Many programs combine them: our team for volume, your experts for the hard cases.
Can you work in the labeling tool we already use?
Yes. MLtwist can set up and run work in third-party tools such as Datasaur and Kili, then pull, check, and post-process the results.
Where does our data live?
In your cloud storage. MLtwist reads from and delivers back to your GCS, S3, or Azure bucket, encrypted at rest.
How do government teams buy?
Through Carahsoft or Google Cloud Marketplace, as well as directly. See the public sector page for details.
Get a human-verified training set
Tell us what you're labeling. We'll scope it with our team, yours, or both — and deliver it versioned, in your format.
Also available through Carahsoft and Google Cloud Marketplace.